Benjamin F Spector @spectorb
pilot of @flappyairplanes. i make ml go brr. benjaminfspector.com Joined October 2020-
Tweets170
-
Followers12K
-
Following358
-
Likes12K
@plugyawn V cool. Dm me, would be glad to help!
@Enigma_AI Congratulations! This is awesome
@evayzh you watch even this at 2x?
math checks out! hadn't thought about it this way before your post but I think another way to view this is that you really just want to max the total shoreline of the system (provided enough low-latency networking). In your example, I think what the smaller-die approach is getting you is really shoreline/$, and allocating enough shoreline to networking allows the collective shoreline to behave as a coherent system.
@levidiamode @karpathy Thanks very much @levidiamode , this is so incredibly kind! Happy to do a follow up video with you if you'd like -- would be glad to talk a bit about Blackwell, megakernels, etc, if useful.
i propose, tonight only, we get to light off a nuke over the pacific. for america's 250th the world can let us have one special firework, just for the occasion
- I saw the whole throughout-interactivity pareto frontier be characterized in real time on the A0 silicon, with the token outputs streamed too. - I went through their codebase for how they do megakernels and thought it was, genuinely, very well done. I actually agree it would be good if they put more of their numbers out in public. (FWIW I did encourage them to. I know why they haven't yet and it does make sense but I am not sure it's correct on net.) But I still dislike your insinuation that everyone around the table is a paid shill, which I think is insulting and also just wrong.
@__tinygrad__ @Etched This is stupid and you should feel bad. I have seen the actual hardware generating tokens at astonishing speeds. You must think very little of the people on this list to believe they would squander their reputations for a few dollars.
Had a chance to dive deep into this with the Etched team, and came away extremely impressed. It's a good chip sir. Their programming model around megakernels is also very simple and controllable and quite well done. Focus here on flop density + scale up seems right. Big kudos to the Etched team!
@InferizeAI Awesome stuff, can't wait to play with it!
@EngramLab Congrats! Very excited to play with what you guys are building!
All reliable clusters are alike; each unreliable cluster is unreliable in its own way.
@hamzaelshafie What a wonderful, in-depth post! I'm immensely appreciative of the effort that must have gone into this. I've added a link to the readme of the TK repo. And footnote (2) is a good idea -- an xor instead of down shuffle would probably save a few instructions!

megakernels remain underrated. if you haven’t dug into them before go look them up! flappy seems to be hinting at some really powerful training megakernel stuff which is sick ex: fully contained training megakernel could be great for automated research

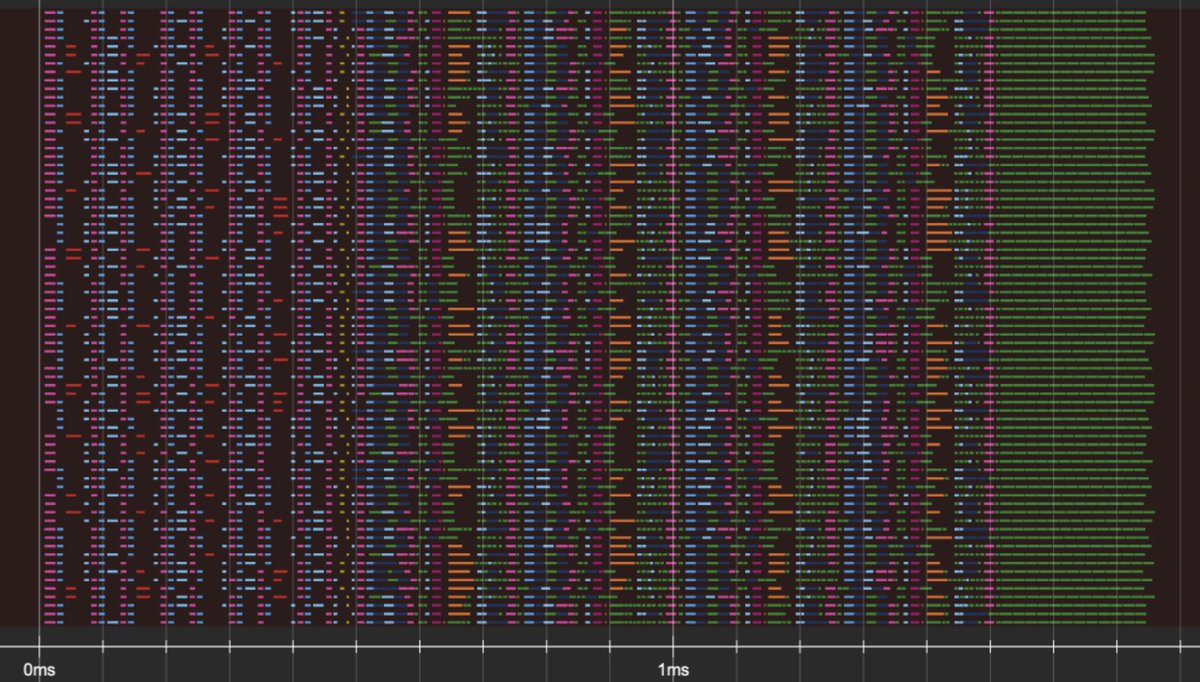
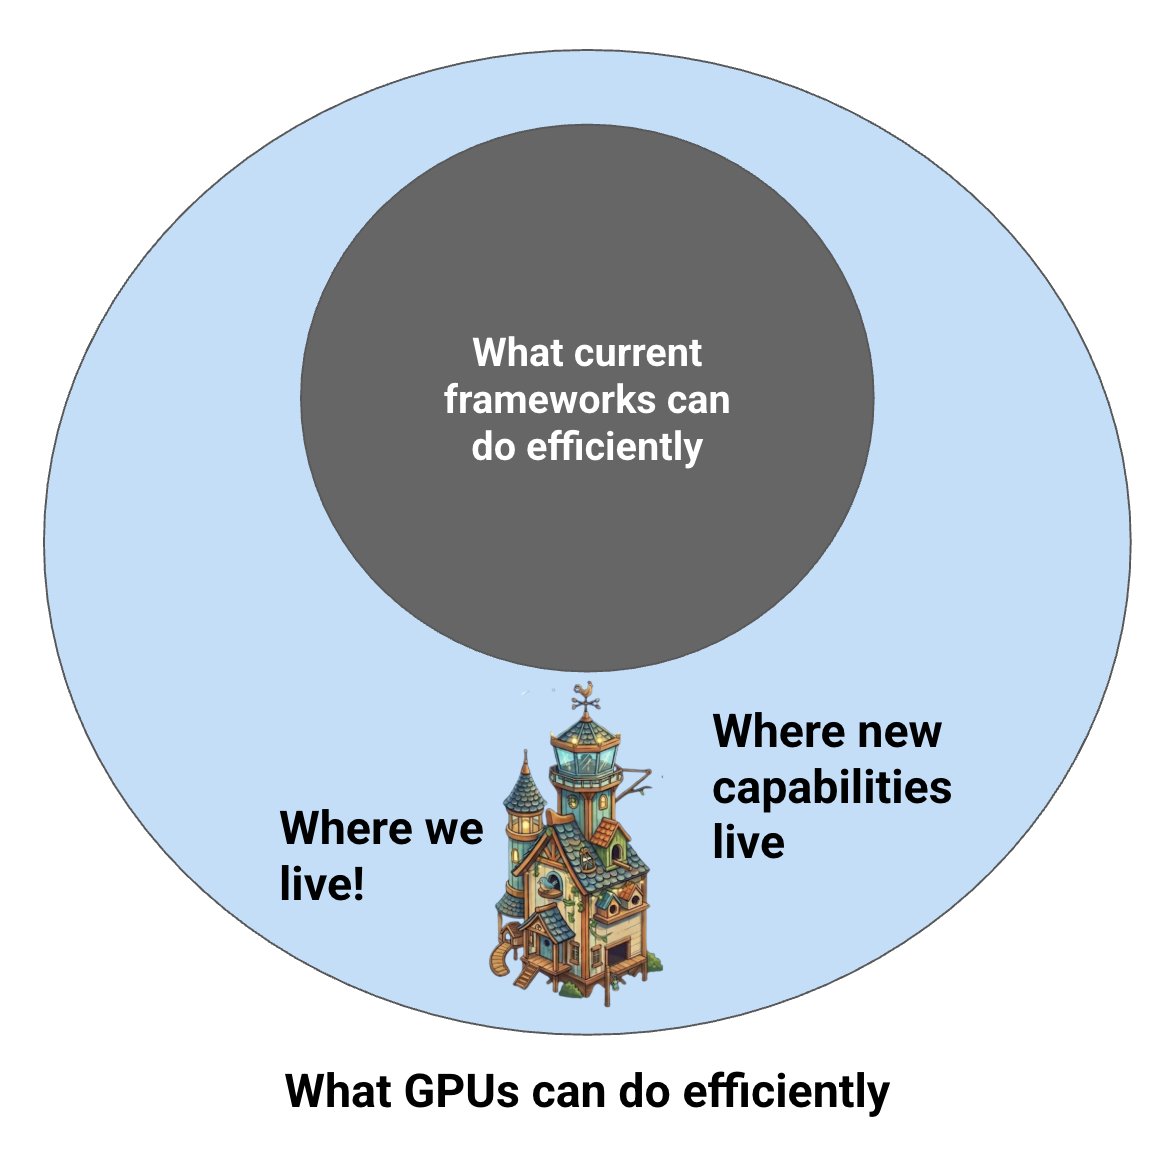
(4/5) One thing we’ve built is a “kittens” virtual machine that takes over the whole GPU and allows new kinds of co-optimization. We can go past the traditional sequential kernel model – for example, fusing entire training runs into a single kernel and even weirder stuff.

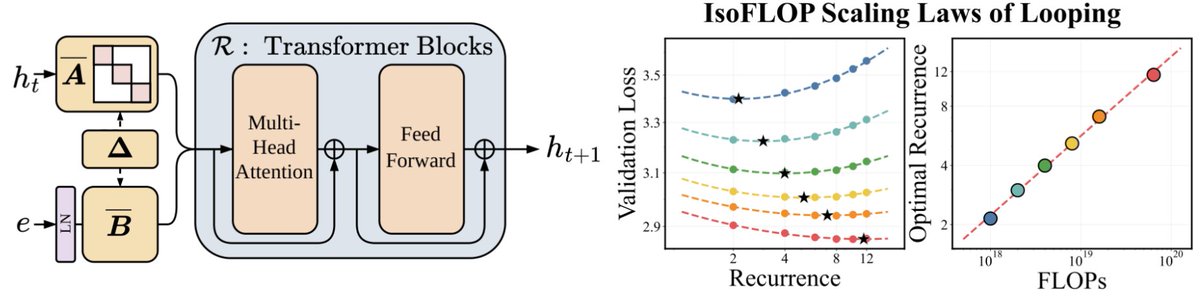
We’ve been thinking a lot about scaling laws, wondering if there is a more effective way to scale FLOPs without increasing parameters. Turns out the answer is YES – by looping blocks of layers during training. We find that predictable scaling laws exist for layer looping, allowing us to use looping to achieve the quality of a Transformer twice the size. Our scaling laws suggest that for a fixed parameter budget, data and looping should be increased in tandem! 🧵👇
@dylan522p @SemiAnalysis_ @Kurnalsalts Ah I meant they'd get physically larger to allow for lower power consumption. The whole thing has to run on like 100W or something? Including memory and whatnot. But this was an offhand comment, I am far from confident I am right.

kurkure momo @idkBro_6769
9 Followers 353 Following

Chenpibaicha @Chenpibaicha300
3 Followers 140 Following
Jasmine @he_jasmine11493
2 Followers 58 Following Strategy & Operations | AI Organization Lead at HealthAI. Building AI teams, products and talent networks. 7 years in executive search. China to global.
x @xvmjnk
0 Followers 28 Following

Al guardkeey gadget �... @AlGuardkeey247
176 Followers 1K Following BIG MUSIC. AN BIG BAGS ON MINDS 💰 💭 AI MIND. GUARD HEART. Time & Guard Matter ⏰🔑 Building to help people 🌊💌 it will com in full💯🤲✊

Mike @mikereadsposts
36 Followers 281 Following
Poorvi @Poorvirealm
0 Followers 104 Following
Devans Gupta @DGVance
76 Followers 523 Following
Victor @victorhdinh
7 Followers 134 Following MSCS student @GeorgiaTech, UG @TuftsUniversity. driven by curiosity and an insatiable appetite for growth. interested in computing and AI
rehaou3o1i239013 @rehaou3o1i68862
1 Followers 23 Following
Harry Thomas @harrybthomas
636 Followers 5K Following High Technology prev first employee @RainmakerCorp
Satoshi Honda サト�... @satoshihondasan
1 Followers 6K Following X no minasan. hajimemashite! dozo yoroshiku.

Ronin 浪人 🗡️ @0xroninakira
137 Followers 3K Following Calm in the chaos. 🌪️ Solo. Self-taught. I play the markets most people fear. 🔥

Moriah Beginner inves... @MoriahBegi38u
5 Followers 195 Following Bitcoin investment have made a lot of people to gain their financial freedom, Learn how to earn extra income online, Profits 💯 guarantee sure.
Katie Haun @katie_haun
135K Followers 870 Following Founder and CEO @HaunVentures. Alum @Coinbase Board, @a16z, @TheJusticeDept, @Stanford, @USSupremeCourt w/Justice Kennedy. Teach from time to time @StanfordGSB.

Ron Kozokin @RKozokin65705
3 Followers 17 Following

Lulu Y Zeng @LuluYZeng
149 Followers 541 Following Product & Growth @Boltzbit AI-native by default, shipping with builders ex-Venture Capital CS @PennEngineers
filip @filipi1ifilip
15 Followers 149 Following
Agata Pustułka @AgataPustulka
1K Followers 375 Following Sr Correspondent @techcrunch, I cover startups, markets & AI prev @openAInewsroom
Kevin Patel @bballkev19
33 Followers 144 Following
Shriteja Patil @_______stp
1 Followers 74 Following
Sunshine Chen @sunshine_cxn
168 Followers 1K Following stats & history @harvard | sometimes @dormroomfund
Arron Acosta @arronacosta
808 Followers 3K Following Machinery Tinkerer • dreamer • MIT Mech E 2010 • RISE Robotics Cofounder • Techstars Boston 2012 • Greentown Labs Alum • Apple alum •Satoshi’s Vision $arron
Carlos Santivañez @CarlosSantivane
28 Followers 986 Following
Eric Chen @OverTheAlps25
20 Followers 3K Following

Alberto Tono @albertotono3
1K Followers 30 Following Applied Scientist @adobe l @Stanford PhD | Founder @CDInstitut | Ex-SR @googledeepmind
Max Scherer @MaxScherer13
0 Followers 1 Following
Calder Russell @CalderDRussell
2 Followers 41 Following
Morad Ali @FRE5408
0 Followers 481 Following
Ronghang Hu @RonghangHu
2K Followers 6K Following multimodal at @SpaceXAI | previously at @Meta FAIR
Rohit (@[email protected]... @s4dr0t1
175 Followers 2K Following security engineer | metalhead | otaku | perpetually curious | resident @CRED_club | views are personal, not my employer's
Alex Freitas @AlexFreitasAI
459 Followers 661 Following AI operator testing agents in production. Evals, reliability failures, fixes that work. YouTube: The AI Engine Room. Founder, Kivik Digital Group.

Simi @SiN57863454
2 Followers 479 Following

Fighter 633 @fighter_633
165 Followers 2K Following
Mathias Lago @gomathie1_
214 Followers 2K Following Visual Media | Web Developer |Tech Support Engineer | Telematics | Design with @adobe suites
RP @im_pin_f
0 Followers 52 Following
QuantumRemix @DalmusDayanti_
276 Followers 2K Following

Alfred Spector @AlfredZSpector
22 Followers 55 Following Alfred Spector is a Professor of Practice in Computer Science at MIT. Previously, CTO at Two Sigma and Global VP of Research & Special Initiatives at Google.


Ashley Zhang @ashley11829
2K Followers 17 Following Next-gen LLM Architecture and Optimizer. Research Scientist @tilderesearch

Yash Patil @ypatil125
11K Followers 652 Following Co-Founder, CEO @appliedcompute 🚂 prev: @OpenAI, @Stanford
Ayaan Hirsi Ali @Ayaan
605K Followers 1K Following Christian, founder @AHAFoundation, fellow @HooverInst, founder & contributing editor @RestoringWest and host of the Ayaan Hirsi Ali Podcast. Opinions my own.

Progyan @plugyawn
2K Followers 933 Following writing as a rehearsal of language. language as a rehearsal of logic. pretraining research
Scott Gray @scottgray76
15K Followers 921 Following Currently independent. Exploring some neuro-inspired AI approaches. Former GPU geek at @OpenAI. He/Him.
Deedy @deedydas
254K Followers 6K Following Partner at @MenloVentures. Investor: Anthropic, OpenRouter, Modal, Wispr, Pangram, Inception, Goodfire, PrimeIntellect prior: Glean, Google Search. Cornell CS.


Can Bölük @_can1357
17K Followers 478 Following BDFL @ https://t.co/MXnNmnVajl I break software for a living, giving back by making LLMs break em less. Lifelong ring-0 resident, LA57 fan, drew a ▲ with dx12 once.
Alon Pluda @AlonPluda
1K Followers 87 Following


Francois Chaubard @FrancoisChauba1
5K Followers 372 Following Visiting Partner YC | PhD AI Stanford | Founder/CEO Focal Systems

Stephanie Palazzolo @steph_palazzolo
23K Followers 5K Following Writing AI Agenda @theinformation, texan, & horror movie aficionado // reach me at [email protected] or on Signal at 979-599-8091
theseriousadult @gallabytes
8K Followers 1K Following father, ML enjoyer @anthropicai. previously @midjourney v2-7
Yoko @stuffyokodraws
15K Followers 2K Following Cartoonist, Engineer, PM, Partner @a16z investing in infra & AI Prev Product lead @HashiCorp, Founding Eng/PM @Transposit. Eng @AppDynamics. Opinions = own.
Allen Wang @a11enhw
437 Followers 740 Following Research @cartesia. Prev. Co-founder @outerport (YC S24), @UWaterloo intern (@meta @linkedin). Erdos number = 4.
Chase Lochmiller @ChaseLochmiller
16K Followers 2K Following CEO and Co-Founder of @CrusoeAI Former @polychain, @jumptrading, @Stanford, @MIT

SemiAnalysis @SemiAnalysis_
165K Followers 31 Following
𝐍𝐢𝐨𝐡 𝐁... @NiohBerg
431K Followers 581 Following Possibly the most famous Iranian Jew on social media | Advocate for Iranian Monarchy Restoration
Josh Wolfe @wolfejosh
274K Followers 8K Following co-founder + partner @ Lux Capital | Trustee @SfiScience Santa Fe Inst | Founding Chair @CiPrep (Brooklyn) | Co-Founder of Carson, Quinn & Bodhi w/ @ltwolfe
Adi @adi_baradwaj
19K Followers 11K Following Founder @Astra_Markets, Prev: @AlamedaResearch, @Google, @Berkeley_EECS. https://t.co/yd2l58oRcv

Zhengyao Jiang @zhengyaojiang
13K Followers 744 Following Cofounder & CEO @WecoAI - automated hill climbing with LLMs. Prev: PhD in ML @UCL_DARK. (Zheng=j-uhng, j as in job; yao=y-aoww)
Nick shirley @nickshirleyy
1.8M Followers 1K Following If you’re reading this hit that follow button. Teaching the world to lear 🌎 Become a subscriber to support 🙏🏼
Alex Peng @alexjpeng
820 Followers 749 Following posttraining @xai, prev fde @cognition, @windsurf, @stanford
swyx @swyx
193K Followers 4K Following achieve ambition with intentionality, intensity, integrity & insanity. affiliations: - @smol_ai - @dxtipshq - @cognition - @aidotengineer - @latentspacepod
Charles 🎉 Frye @charles_irl
20K Followers 3K Following memer of technical staff at @modal. he/him. ex @full_stack_dl, @weights_biases (acq. @CoreWeave), phd Berkeley @Redwood_Neuro.

Dhruv π @dhruv31415
1K Followers 276 Following pretraining @openai, previously @tilderesearch Opinions are my own, not reflective.

Balogun @balogun
317K Followers 0 Following

You might like