Mingyu Ding @dingmyu
Assistant Professor @UNC @unccs | IDEAL@UNC | Dexterous/Loco-Manipulation | #robotics, #embodiedAI, #3Dvision, #foundationmodels. dingmyu.github.io Joined August 2024-
Tweets35
-
Followers493
-
Following76
-
Likes59
Evaluated across four benchmarks: LIBERO, RoboTwin, RoboCasa, and RoboDojo. 📖 Blog: tianqi-zh.github.io/BenchMend/ 🎥 Rollouts: huggingface.co/spaces/benchme…
A robot can follow a reasonable interpretation of an instruction and still fail the benchmark. Meet BenchMend: we use GPT-6-Astra to uncover instruction–verifier gaps in robotics benchmarks, then repair the wording while preserving success checkers and recorded demonstrations.
Excited to share @AlanZhang0928's BenchMend! Robots may fail a benchmark not because of wrong actions, but a misaligned instruction-verifier. GPT6 Astra can repair this with minimal change, pointing toward benchmarks that uncover their failure modes and iteratively self-improve.
A robot can follow a reasonable interpretation of an instruction and still fail the benchmark. Meet BenchMend: we use GPT-6-Astra to uncover instruction–verifier gaps in robotics benchmarks, then repair the wording while preserving success checkers and recorded demonstrations.

Today we are introducing Dyna-2, a world-action model pre-trained on one million hours of human video. At this scale, for the first time, we discovered several new scaling laws: • world-action models exhibit scaling law on human data across four orders of magnitude, from 1000 to 1,000,000 hours, • this human data scaling law implied a scaling law on never seen robot data, • both data and objective matter; world modeling and scaling on video data are essential for cross-embodiment scaling transfer to emerge 🧵
Thanks Shuran! Really appreciate your support. Website: handroid.org Also excited to see the amazing and inspiring Transformer Transformer for co-design transformer-transformer.github.io
Check out the @dingmyu and the team's amazing website to get the build details on how to build your own Handroid :)
Thanks Haochen! It was a pleasure collaborating with you as well. Your insights were incredibly valuable and look forward to pushing this direction even further together.
This is exactly the kind of "transformer" I imagine. Creatively extending the otherwise limited workspace of a robot arm in a way that just makes sense. A perfect example of a brilliant idea + amazing execution. Enjoyed collaborating with the team a lot!
Great work with @RuoguLi0425, Chenyang Ma, @Ske_Vinci, Zhenyu Wei, @YaoYunchao, @HaochenShi74, Karen Liu, @SongShuran 🌐 Project: handroid.org 📄 Paper: arxiv.org/abs/2607.16187 CAD models and the complete BOM are also available on the project website.
🤖 A robot that transforms between humanoid and dexterous hand? Introducing Handroid, a reconfigurable robot with a shared 27-DoF body 🖐️→🚶→🖐️: • The same joints, different roles • Expanded robot task space • Shared sensing and control interfaces handroid.org
Humanoids shouldn’t have to stop before they act. CoorDex enables humanoids to walk and manipulate simultaneously by coordinating body and dexhand motion priors in latent space. AnyBody enables coordinated whole-body control from sparse keypoints, while adapting to environment.
We just released WatchAct, a benchmark for behavior-grounded robot manipulation (covered in the talk below). The robot has to watch a human video, infer what was done, make a plan, and then execute it. The best VLM (Gemini-3.1-Pro) only reaches 36.8% planning success rate, so still plenty of room for improvement. Paper: arxiv.org/abs/2606.26443 Project: baiqi-li.github.io/watchact_page/ Code: github.com/Baiqi-Li/Watch… Dataset: huggingface.co/datasets/Baiqi… w/ @baiqil0203 @cezhhh @yuffishh @dingmyu
Sharing my CVPR 2026 talk from the Vision for Intelligent Task Assistants workshop: "From Perception to Agency: The Cognitive Stack for Video Task Assistants." It covers our SVI-Bench project (svi-bench.github.io) plus a video+robotics project we'll release soon. w/
What if humanoids could manipulate without stopping, using a high-DoF dexterous hand? 🚨We introduce CoorDex, a learning pipeline for continuous dexterous humanoid loco-manipulation — coordinating whole-body motion and high-DoF finger control while the robot is still moving. This enables a Unitree G1 with a 20-DoF WUJI dexterous hand to: 🤖 grasp and carry a bottle while walking 🚪 open a fridge while stepping backward 🔄 pick up a cube and turn 180° 🔗Project page: skevinci.github.io/coordex/ 📜Paper: arxiv.org/abs/2606.23680 🧵(1/n)
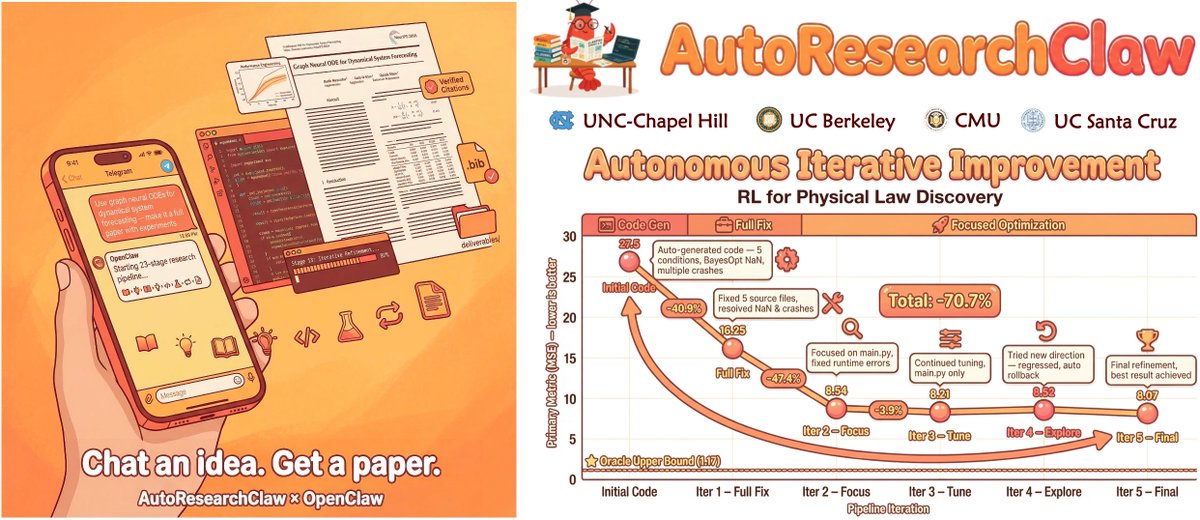
🔥 AutoResearchClaw tech report + v0.5.0 just dropped. 12,300+⭐ on GitHub. Two big additions this release: 🧪 1/ Domain-Expert Agents in the experiment stage: Specialized agents for high-energy physics, biology, and more. Real domain tools + knowledge plugged in — not a generic LLM pretending to run experiments. 📊 2/ ARC-Bench A 55-topic benchmark across ML, HEP, quantum physics, biology, and statistics. One of the broadest cross-disciplinary evaluations for autonomous research ever released. 🏆 The numbers: → Beats AI Scientist v2 by 54.7% on ARC-Bench → 7-mode HITL (human-in-the-loop) ablation: targeted intervention > full autonomy OR exhaustive oversight. The thesis (still): real research isn't a pipeline. Hypotheses fail. Lessons compound. AutoResearchClaw is a research amplifier — not a paper generator. 📄 Tech report: arxiv.org/abs/2605.20025 💻 Code: github.com/aiming-lab/Aut… Thanks @itsJiaqiLiu and @StephenQS0710 who lead the work and all other contributors @HaonianJi, @lillianwei423, @XinyeYee, @richardxp888, @HaoqinT, @Xinyu2ML, @WeitongZhang, @jiahengzhang96, @LINJIEFUN, @linjunz_stat, @yuyinzhou_cs, @CaimingXiong, @james_y_zou, @ZhengBerkeley, @cihangxie, @dingmyu

Everyone's excited about Karpathy's autoresearch that automates the experiment loop. We automated the whole damn thing. 🦞 Meet AutoResearchClaw: one message in, full conference paper out. Real experiments. Real citations. Real code. No human in the loop. One message in →
🤖Can robots play Texas Hold’em? 🤔 We introduce DexHoldem, a real-world benchmark for dexterous manipulation and embodied agents. After fine-tuning leading VLAs and pairing them with frontier agents, we found: Robots can move the chips — sometimes. Agents can read the table state — sometimes. Unfortunately, poker requires both to happen correctly in the same hand. So no, robots are not ready to take your money at the casino — yet. More below 👇
🚀Introducing DIAL: Decoupling Intent and Action via Latent World Modeling for End-to-End VLAs. By formulating latent visual foresight as a differentiable structural bottleneck, DIAL strictly grounds motor control in the VLM’s intent. This architecture alleviates representation collapse during joint optimization, enabling the model to absorb cross-embodiment human data for robust generalization, while mastering complex multi-stage coordination in the real world. 🚀Paper, code, and project page released! Fully open-sourced! Paper: arxiv.org/pdf/2603.29844 Project page: xpeng-robotics.github.io/dial/ Code: github.com/xpeng-robotics… Congrats to @ChenYi041699 and many thanks to our awesome collaborators @tttoaster_ @dingmyu @ge_yixiao
🚀 AutoResearchClaw v0.4.0 is here — almost 10K⭐ in just over 2 weeks! Now supporting both fully autonomous AND human-AI co-pilot modes — you choose your level of involvement. What's new: 🤝 6 intervention modes — full-auto, gate-only, checkpoint, step-by-step, co-pilot, and custom. Same powerful 23-stage pipeline, your level of control. 🧪 Idea Workshop — brainstorm and refine hypotheses with AI before committing to a direction 📊 Baseline Navigator — review and customize experiment designs before execution ✍️ Paper Co-Writer — draft papers section-by-section, collaboratively 🧠 SmartPause — the system learns when to pause and ask for your input based on confidence levels 💰 Cost Guardrails — budget alerts at 50/80/100% so you never get surprised 🔀 Pipeline Branching — explore multiple hypotheses in parallel, compare, and merge the best Want full automation? It still does that. Want to stay in the loop? Now you can, at exactly the granularity you want. Try it 👉: github.com/aiming-lab/Aut… Kudos to the team @JiaqiLiu835914, @richardxp888, @lillianwei423, @StephenQS0710, @Xinyu2ML, @HaoqinT, @jiahengzhang96, @yuyinzhou_cs, @ZhengBerkeley, @cihangxie, @dingmyu, etc.

Do Vision-Language-Action Models truly follow your language instructions? We present When Vision Overrides Language: Evaluating and Mitigating Counterfactual Failures in VLAs. They promise to ground language instructions in robot control, yet in practice, often fail to follow language faithfully. 📄 Paper: arxiv.org/abs/2602.17659 🌐 Project: vla-va.github.io 💡 Highlights Vision shortcuts and counterfactual failures. When given instructions that lack strong scene-specific supervision, they default to well-learned scene-specific behaviors regardless of language intent. Counterfactual benchmark. We introduce LIBERO-CF, the first counterfactual benchmark for evaluating language following in VLAs. Our evaluation reveals that counterfactual failures are prevalent yet underexplored across state-of-the-art VLAs. Our solution. We propose Counterfactual Action Guidance (CAG), a simple plug-and-play dual-branch inference scheme that strengthens language conditioning without changing pretrained VLA architectures or weights. Experiments. CAG is effective across multiple dimensions of language grounding, consistently improving both language grounding and task success on under-observed tasks. #VLA #Robotics #Vision #Language
Can we build a universal brain for all dexterous robot hands? Zhenyu Wei, Yunchao Yao, and Mingyu Ding from University of North Carolina at Chapel Hill just tackled this! By creating a "canonical representation," they translate all kinds of dexterous robot hands into a single, unified description and control language. This allows a single AI policy to understand and control them all. The result: policies that instantly generalize to any new robot hand design, achieving an 81.9% zero-shot success rate on unseen hands and opening the door to universal dexterous manipulation. One Hand to Rule Them All: Canonical Representations for Unified Dexterous Manipulation Project: zhenyuwei2003.github.io/OHRA/ Paper: arxiv.org/abs/2602.16712 Code: github.com/zhenyuwei2003/… Our report: mp.weixin.qq.com/s/cp15BVTkxkZM… 📬 #PapersAccepted by Jiqizhixin
Found an impersonation account @mingyding pretending to be me. I only have one account. Please do not interact with the fake account and help report it if possible, thanks!
@cakeyan9 @mingyding Good news: they even credited me with other professors’ papers, hope that’s true
@Hongyu_Lii Maybe I'm the fake one here lol
@xyz2maureen @mingyding Perhaps they bought them from Taobao?🤣


Yuze Zhu @ZhuYuze83032
0 Followers 18 Following

yy @yywngye
60 Followers 4K Following
Guozheng Ma @Guozheng_Ma
221 Followers 473 Following PhD student @NTUsg, working on Deep Reinforcement Learning.


Huan Yin @HuanYINN
2 Followers 52 Following
Miguel @Kaweees1
1K Followers 1K Following Prev. Roboticist @dimensionalos, Humanoids & Chip design agents @nvidia GEAR.
Vanadium @YufanZuo_
3 Followers 149 Following


Zach Pan @ZacharyPan
40 Followers 945 Following I like to think in systems and build them. ex VC Analyst @ 5Y Capital & FreeS Fund. CMU'18 PhD @ SJTU in AI + Biomed Eng
Yogesh Ghaturle @yogesh_origin
425 Followers 2K Following CEO & Founder @origin_autonomy | Building Time Machines for Construction! Ex-Founder - Perpule (Acq by Amazon) | AI x Robotics | ACM-ICPC World Finalist
Hamza @hamzscenes
11 Followers 33 Following Building websites from first principles Building robotics that mimic the natural world @ DavinciRobots
Action Intelligence R... @actintresearch
5 Followers 376 Following
Weikun Peng @PengWeikun
21 Followers 144 Following I am a first-year PhD student at SFU GRUVI lab, working with Professor Manolis Savva. I'm broadly interested in computer graphics and robotics.
Yifei Wang @WangYw251
470 Followers 425 Following Research #representationlearning #diffusion; PhD student @RiceUniversity; Visiting student @JohnsHopkins; Prev @PKU1898

FFEI @KKaren__26
1 Followers 88 Following
Robot-insight @Robotinsight11
4 Followers 19 Following Professional Embodied Intelligence Engineer (focusing on secondary development of Unitree) Shanghai Premier Agent
Soham Ojha @Ojhattu
34 Followers 450 Following Co-Founder @EnotriumAI | UAV and Quadcopter fanatic | Prev: @UMDPhysics | @CERN
ws @chrsow
52 Followers 2K Following
Gao Yi @EthanGaoE
0 Followers 69 Following

Meridian Chen @mihayouxixixi
0 Followers 252 Following

Jing Wang @JingWJ6
154 Followers 793 Following Cofounder @ DeepBuild | Data and deployments infrastructure for Physical AI | CMU
Shikun (Oliver) Ban @OliverBan2
70 Followers 899 Following MSR @CMU_Robotics | Prev @PKU1898 🦾🤖🌍💃🕺he/him
Langzhe Gu @Grange_007
6 Followers 158 Following
Zhexi Luo @ZhexiLuo2026
2 Followers 72 Following
Varun Bondalapati @bonvarun
21 Followers 2K Following
Wenqiao Li @liwenjiao2
2 Followers 227 Following Ph.d in @sjtu1896, intern in BigAI, @SharpaRobotics Supervised by @siyuanhuang95, @ChuanWen15 Research focus on dexterous manipulation & computer vision
Caspian @xhgxhgxhg45646
2 Followers 199 Following
Yunchao Zhang @M_YunchaoZhang
21 Followers 325 Following PhD @hkudatascience. Previously B.Eng. in CS @ZJU_China. Unsupervised learning, Embodied AI
Huayi Wang @HuayiWang04
283 Followers 209 Following Hi! I am a final-year undergraduate student at @sjtu1896. I am interested in Robot Learning and Humanoid Robots. Website: https://t.co/S5lYcsqWhP


weison_pan @Weison038
8 Followers 487 Following
Nishaanth Kanna @nishaanthkanna
2 Followers 832 Following
Junjie Zhang @JunjieZhan71984
2 Followers 29 Following
Léo @LeoKharon
2K Followers 486 Following Robotics research & updates. Co-host @roboticsstack, the weekly pod on what's actually shipping in 🤖
yuri @jjfjj36716650
10 Followers 929 Following
Zhen Wu @zhenkirito123
2K Followers 415 Following Amazon FAR (Frontier AI & Robotics). CS @Stanford. Humanoid Robots & Character Animation 🤖
Shane Carter @ShaneCarter25
538 Followers 7K Following
わっしゃー @washer_hobby2
456 Followers 2K Following 前アカウントが凍りました 20↑ 趣味のアカウント, P(奈緒リーリヤ樹里千早),副業でロボットHW屋さん
Xiong Zeng @XiongZeng111
425 Followers 2K Following PostDoc for robot learning with Prof. Wei Zhang @CLEARLabChina, Ph.D. @UMichECE.

Bingao Chen @bingao_chen
97 Followers 442 Following Undergrad @Tsinghua_Uni | Intern @Stanford | Prev @nyuniversity

Generalist @GeneralistAI
25K Followers 23 Following Generalist is an AI robotics company building general intelligence for the physical world and making it useful to everyone.
Biwei Huang @huang_biwei
5K Followers 252 Following Founder @AetherLab_AI Assistant Professor @HDSIUCSD @UCSanDiego Causal World Model, Causality-driven Agentic System for the next AI paradigm
Léo @LeoKharon
2K Followers 486 Following Robotics research & updates. Co-host @roboticsstack, the weekly pod on what's actually shipping in 🤖
Monica Xie @immonicax
2K Followers 4K Following Building @dynarobotics | Podcast “OnBoard!”| ex @MatrixPartners @AWS @zhenfund | views are my own
Lu Ling @LuLing26466911
676 Followers 659 Following prev. @WorldLabs @NVIDIAAI丨PhD @PurdueCS丨#AI 丨#ComputerVision丨Agentic AI丨4D/3D GenAI丨 Multimodals
Peter Yichen Chen @peterchencyc
1K Followers 486 Following UBC PhysAI Lab – Hiring postdocs, PhD students, and research interns
Hao Zhao @HaoZhao_AIRSUN
1K Followers 561 Following https://t.co/l52lTpdO16 Computer vision is good, have fun.
Binghao Huang ✈️I... @binghao_huang
3K Followers 1K Following CS PhD student @Columbia advised by @YunzhuLiYZ. MechE @UCSD w/ @xiaolonw. Research Intern @amazon FAR . Ex-@NVIDIA. Embodied AI/Robot Learning.
Shuran Song @SongShuran
16K Followers 564 Following Assistant Professor @Stanford University working on #Robotics #AI #ComputerVision

Homanga Bharadhwaj @mangahomanga
4K Followers 1K Following Assistant Professor of CS @JohnsHopkins | Hater of hot takes. Lover of analyses.
Sikai Li ✈️IROS 2... @Ske_Vinci
95 Followers 388 Following Intern @gs_ai_ | PhD Student @unccs | RA @upennnlp | BSE @UMichCSE @sjtu1896 | Working on humanoid #robotics
Feng Chen @Winniechen02
268 Followers 155 Following Ph.D. student. at the University of Hong Kong, advised by prof. Yi Ma Graduated from IIIS Tsinghua University 2024 (Yao Class)
Zhiwen(Aaron) Fan @zhiwen_fan_
2K Followers 398 Following Assistant Prof @ Texas A&M ECE @TAMU | World Model and other Spatial Foundation Models
Jiaqi Liu @itsJiaqiLiu
211 Followers 450 Following CS PhD student @UNC @unccs |Author of AutoHarness, AutoResearchClaw,SimpleMem
Cihang Xie @cihangxie
4K Followers 1K Following Assistant Professor, @BaskinEng; PhD, @JHUCompSci; @Facebook Fellowship Recipient; 🐱
Yunzhu Li @YunzhuLiYZ
11K Followers 579 Following Co-Founder of SceniX (now part of @theworldlabs) | Assistant Professor @Columbia @ColumbiaCompSci | Former postdoc @Stanford @StanfordSVL | PhD @MIT_CSAIL
Zixian Liu @ZixianLiu03
94 Followers 298 Following 1st PhD student @unccs, prev undergrad @Tsinghua_Uni
Yixuan Wang @YXWangBot
3K Followers 1K Following CS Ph.D. student @Columbia & Research Scientist @NVIDIARobotic | Prev. Meta FAIR Embodied AI, Boston Dynamics AI Institute, Google X #Vision #Robotics #Learning

Robotics Papers @OWW
3K Followers 2 Following New Robotics papers from https://t.co/QghHeRjSAH: robotics. Thank you to arXiv for use of its open access interoperability.
Harish Ravichandar @h_ravichandar
900 Followers 1K Following Structural priors for frugal and self-sufficient robot learning. Robotics & AI Faculty @GeorgiaTech @ICatGT @GTrobotics @mlatgt
Jason Ren @RenZhongzheng
501 Followers 859 Following Assistant Professor @unccs Research Scientist @allen_ai
Marco Pavone @drmapavone
6K Followers 70 Following Prof @Stanford, Distinguished Research Scientist and AV research lead @nvidia. PhD from @MITAeroAstro. Robotics, autonomous systems, AI. Opinions are my own.
Qixing Huang @qixing_huang
5K Followers 376 Following I am an associate professor at UT Austin. I do research at the intersection of computer graphics, computer vision, and machine learning.
Anyi Rao @raoanyi
2K Followers 981 Following Assistant Professor @HKUST | AI for Creativity | ex @Stanford @Meta @RealityLabs @UofT | Works #ControlNet #AnimateDiff @cveu_workshop
Xihui Liu @XihuiLiu
2K Followers 215 Following Assistant Professor @ HKU. Previous Postdoc @ UC Berkeley and PhD @ CUHK MMLab
Salesforce AI Researc... @SFResearch
20K Followers 430 Following We advance state-of-the-art #AI techniques paving the path for innovative products at @Salesforce. Focus areas: #AIAgents, #EnterpriseAI, #EGI, and #TrustedAI.
Zhiyang (Frank) Dou @frankzydou
2K Followers 2K Following PhD student @MIT_CSAIL. MPhil @HKUniversity. Ex-visiting @Penn. Dynamics Modeling, Physical AI, Robotics, Sim, Geometry, Control, AIGC. 🦋https://t.co/YpydZBLKs1
Xin Eric Wang @xwang_lk
22K Followers 1K Following Professor @ucsantabarbara. Head of Research @SimularAI. Director @ucsbcrml @UCSB_AI. Build the Science of AI Agents. AI for Humanity in the long run.
Yinghao Xu @YinghaoXu1
4K Followers 174 Following Assistant Professor in @HKUST | prev: Research Lead @robbyant_brain Postdoc @Stanford | Computer vision forever
USPS Help @USPSHelp
129K Followers 23K Following Welcome to the U.S. Postal Service official Social Customer Response site. Hours of Operation: M-F: 8am-10pm ET. Sat: 9:30am-6:00pm ET. Closed Sunday.
U.S. Postal Service @USPS
359K Followers 121 Following The official X account of the United States Postal Service, managed by the Social Media staff at USPS HQ. For customer service, please follow and DM @USPSHelp.
Xueyan Zou @xyz2maureen
3K Followers 191 Following Assistant Professor @Tsinghua_Uni prev. PostDoc 🤖 @UCSDJacobs; PhD 🎓 @UWMadison; Intern @MSFTResearch @BytedanceTalk
Jeff Dean @JeffDean
528K Followers 6K Following Co-founder & CEO of Discovery Loop. Former Chief Scientist, Google. Helped build many Google products, TPUs, Gemini, TensorFlow, MapReduce, Bigtable, ...
Yu Fang @yuffishh
163 Followers 242 Following CS PhD student @unccs. Embodied AI and Robot Learning. Prev Research Intern @SFResearch.
Jaehong Yoon @jaeh0ng_yoon
2K Followers 954 Following Assistant Professor @ntusg CCDS | Prv: @unc_ai_group @MLAI_KAIST @MSFTResearch | Trustworthy & Continually Adaptable Multimodal AI


Seth Z. Zhao @sethzhao506
59 Followers 151 Following CS PhD Student @ UCLA | Prev @ UC Berkeley | Qualcomm/Vals AI Fellow
Zhecheng Yuan @fancy_yzc
716 Followers 647 Following @PokeBot_Global. Final year PhD @Tsinghua University, IIIS.
Shao-Yuan Lo @shaoyuanlo
265 Followers 206 Following Assistant Professor @NTU_TW | PhD @JohnsHopkins | Trustworthy AI, Machine Learning, Multimodal Models
Danielle Szafir @dalbersszafir
2K Followers 2K Following Associate Professor in CS at UNC-Chapel Hill. Research crosses visualization, cognitive science, data science, and MR. Mom, hockey player, golfer, & crossfitter
Pan Xu @iampanxu
2K Followers 1K Following Assistant Prof. @DukeU | Previously @Caltech @UCLA | Views are my own | he/him/his 🌈. 🦋: https://t.co/92GCUj1jvL
Shao-Hua Sun @shaohua0116
4K Followers 1K Following Assistant Professor @ National Taiwan University (NTU) | CS Ph.D. @USC | Robot Learning, RL, Program Synthesis | 台大電機系助理教授 | NeurIPS 2026 Workshop Chair
Chenfeng_X @Chenfeng_X
2K Followers 1K Following Assistant Professor @UTCompSci, PhD @UCBerkeley. Working on something really worksTrends for United States
You might like